Ground Truth Capture
Capture technology running inside licensed games. Every signal a sensor rig approximates, logged exactly, on one clock.
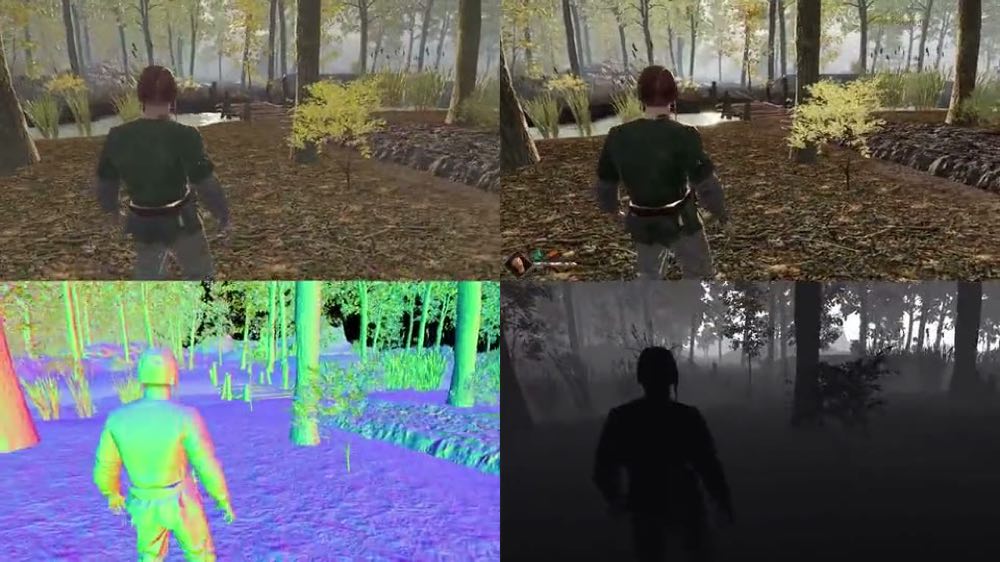
A session as it plays: RGB, normals and depth beside the keys as the player presses them.
Real-world capture is expensive because the world hides its labels.
A game engine doesn't. Everything a rig estimates is already a number inside the simulation. We log it.
| Signal | Real-world source | What it costs there | Origin Lab, from the engine |
|---|---|---|---|
| Depth | lidar, stereo rigs | sparse, noisy, per rig-hour | exact, per pixel, per frame |
| Pose & skeleton | mocap suits, studios | per session, drifts | every entity, every tick |
| Segmentation | human annotation | priced per frame, weeks out | exact, zero latency |
| Actions | inferred from video | lossy, intent unknown | true inputs, logged |
| Events & state | hand labeling | sampled, inconsistent | full state, every tick |
| Edge cases | staged, or waited for | rare, sometimes dangerous | scripted on demand |
Action prediction drops substantially on environments never seen in training. Tested across 193 games.
NeurIPS 2026 · Decodable, Not Transferable ↗100× more egocentric video models the agent well; object fidelity stays far lower and improves slowly.
TRI + CMU · 30,000 Hours of Egocentric Video ↗The misses share a cause: video without actions, states or metric depth. The engine logs all three on one clock.
Origin Lab25 modalities, in three tiers.
Core ships in every hour. Add-ons come a la carte. Premium is scoped and captured per order. Everything frame-synced on one clock, at 60 fps. Select a signal to inspect the recorded evidence.
One recorded licensed session drives every preview. Switching visual signals carries the clock. Data overlays can be toggled independently and stacked.
CORE · 9 9 core modalities in every hour, 60 fps, frame-synced on one clock, 100,000+ hours ready to ship.
ADD-ONS · 6 6 modalities, chosen a la carte, ready on part of the catalog and captured to order for the rest.
PREMIUM · 10 10 modalities, scoped and captured per order.
Capture services on top: custom tasks and scenarios, statistical coverage analysis, player webcam and mic with written consent.
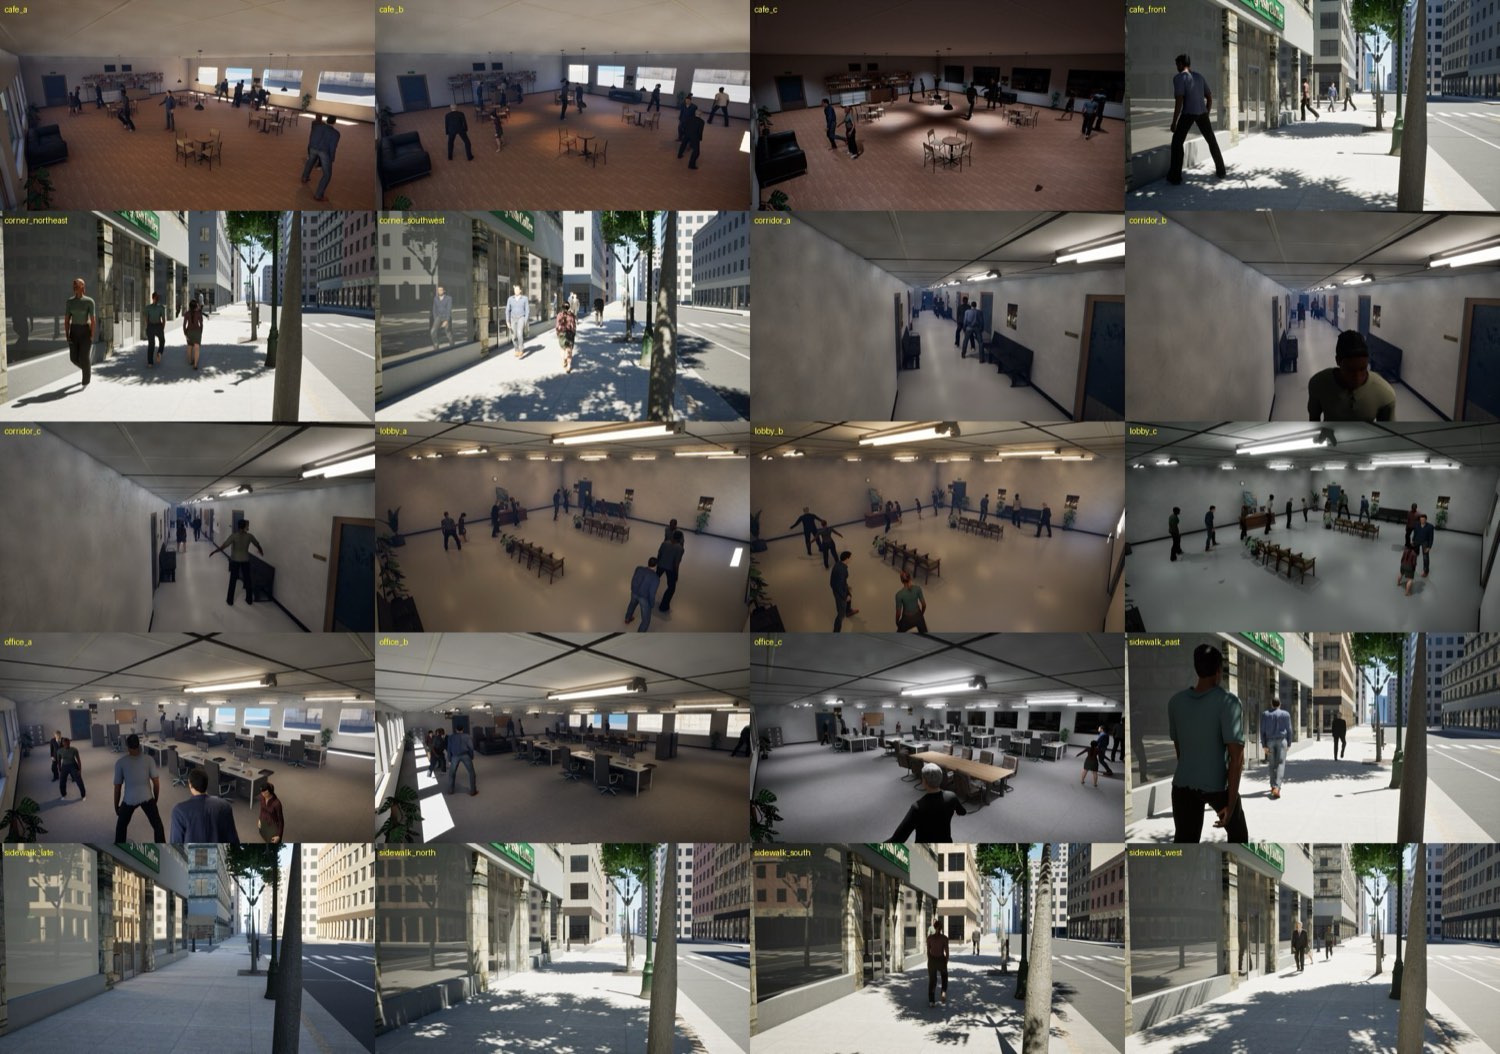
Fixed cameras, one environment, synchronized.
Twenty cameras across a cafe, a lobby, an office and the streets between them, all watching everyday human activity on one clock. Built for teams that train on people moving through real spaces.
Every delivery is a record you can audit.
Each session ships as synchronized tracks with its capture log: every frame, every event, every gap accounted for. This is a recorded 1:01 session, as we QA it.
Track overview from a recorded delivery. Albedo is intentionally absent: modality selection is configurable.
We don't collect footage. We commission it.
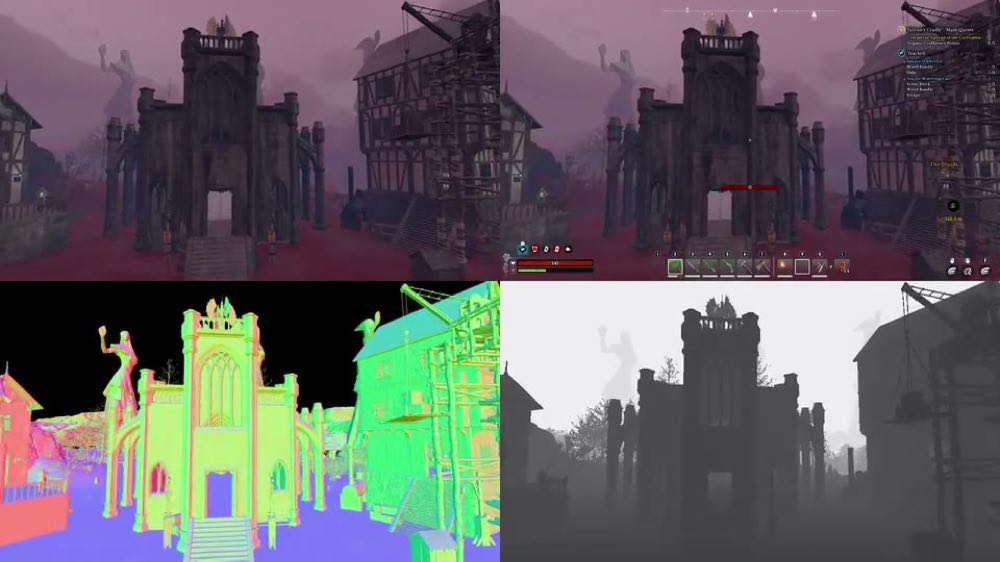
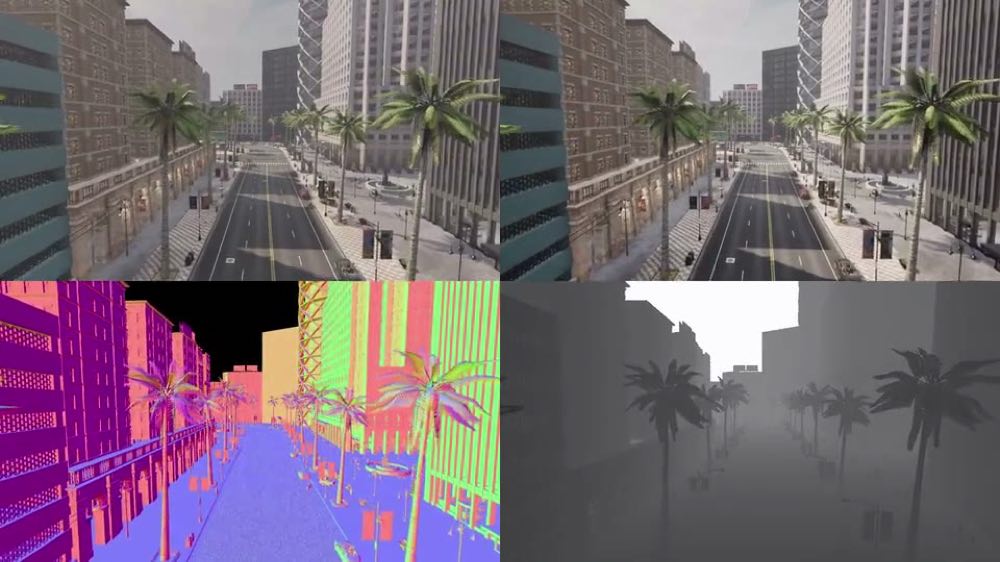
Every order is custom work. Paid capturers play to a mission list: the night drive, the crowded hub, the synchronized multiplayer fight, the behavior your model has never seen. Your task picks the signals, too: rendering teams take RGB, depth, normals and segmentation; geometry teams take posed RGB-D and multi-view; action and behavior teams take inputs, events and state. You specify coverage up front and we measure it on delivery, so you pay for new states, not repeated hours.
Combat: fast motion, many skeletons in frame
However your model needs to see it